

Reliable Salesforce MuleSoft Mule-Dev-301 Dumps PDF Jun 01, 2026 Recently Updated Questions
Pass Your Salesforce Mule-Dev-301 Exam with Correct 62 Questions and Answers
NEW QUESTION # 27
A developer is working on a project that requires encrypting all data before sending it to a backend application. To accomplish this, the developer will use PGP encryption in the Mule 4 Cryptography module.
What is required to encrypt the data before sending it to the backend application?
- A. The application needs to both the private and public keys to encrypt the data
- B. The application needs the private key from the backend service to encrypt the data
- C. The application needs to configure HTTPS TLS context information to encrypt the data
- D. The application needs the public key from the backend service to encrypt the data
Answer: D
Explanation:
To encrypt the data before sending it to the backend application using PGP encryption, the application needs the public key from the backend service. PGP encryption uses a public-key cryptography system, which means that each party has a pair of keys: a public key and a private key. The public key is used to encrypt data, and the private key is used to decrypt data. Therefore, to encrypt data for a specific recipient (the backend service), the application needs to use the recipient's public key. The recipient can then use its own private key to decrypt the data. Reference: https://docs.mulesoft.com/mule-runtime/4.3/cryptography-pgp
NEW QUESTION # 28
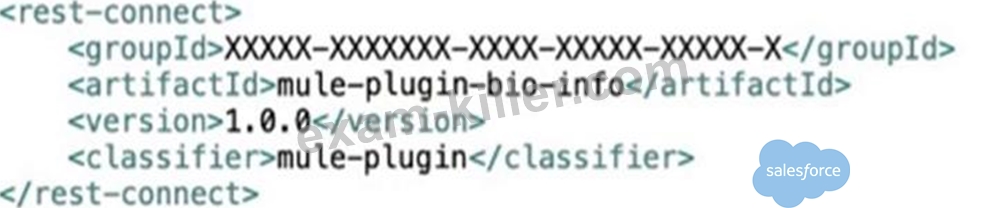
Refer to the exhibits.
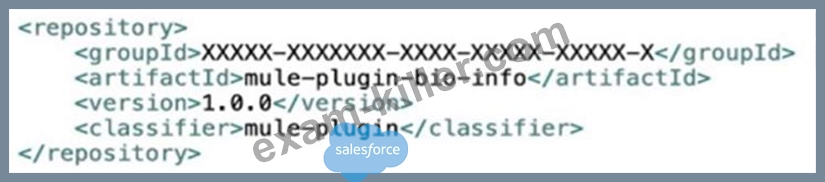
Bioinfo System API is implemented and published to Anypoint Exchange. A developer wants to invoke this API using its REST Connector.
What should be added to the POM?
- A.
- B.
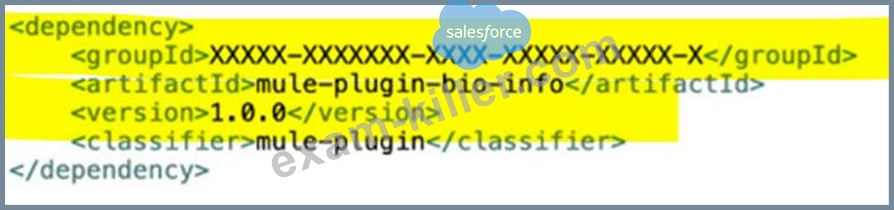
- C.
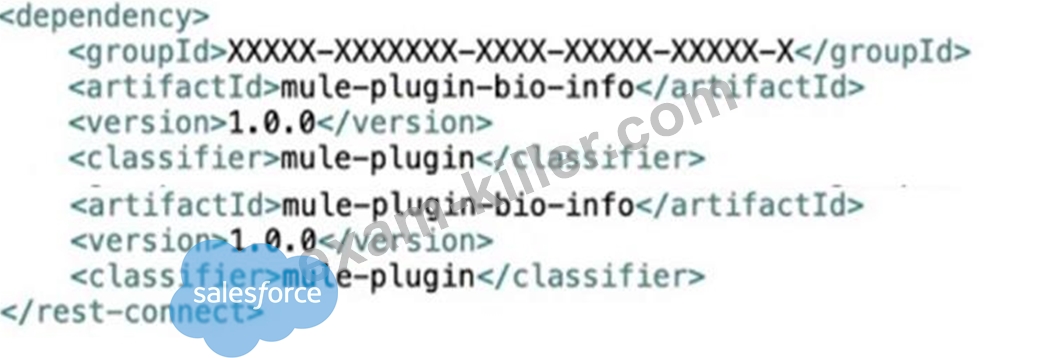
- D.
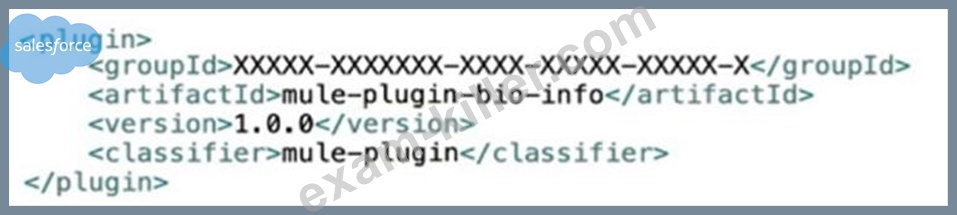
- E.
Answer: D
Explanation:
To invoke Bioinfo System API using its REST Connector, option E should be added to the pom.xml file. This option adds a dependency for Bioinfo System API REST Connector with its group ID, artifact ID, version, classifier, and type. The classifier specifies that it is a REST Connector (raml-client), and the type specifies that it is a Mule plugin (mule-plugin). Reference: https://docs.mulesoft.com/apikit/4.x/apikit-4-generate-from-rest-api-task#add-the-api-dependency-to-the-pom-file
NEW QUESTION # 29
A custom policy needs to be developed to intercept all cutbound HTTP requests made by Mule applications.
Which XML element must be used to intercept outbound HTTP requests?
- A. http-policy:processor
- B. htt-policy:operation
- C. http-policy:source
- D. It is not possible to intercept outgoing HTTP requests, only inbound requests
Answer: C
Explanation:
The http-policy:processor element is used to intercept outbound HTTP requests made by Mule applications. It allows customizing the request before it is sent to the target API and modifying the response after it is received from the target API. Reference: https://docs.mulesoft.com/api-manager/2.x/policy-mule4-custom-policy#policy-xml-file
NEW QUESTION # 30
When a client and server are exchanging messages during the mTLS handshake, what is being agreed on during the cipher suite exchange?
- A. A protocol
- B. The TLS version
- C. The Public key format
- D. An encryption algorithm
Answer: D
Explanation:
A cipher suite is a set of cryptographic algorithms that are used to secure the communication between a client and a server. A cipher suite consists of four components: a key exchange algorithm, an authentication algorithm, an encryption algorithm, and a message authentication code (MAC) algorithm. During the cipher suite exchange, the client and the server agree on which encryption algorithm to use for encrypting and decrypting the data. Reference: https://docs.mulesoft.com/mule-runtime/4.3/tls-configuration#cipher-suites
NEW QUESTION # 31
A Mule implementation uses a HTTP Request within an Unit Successful scope to connect to an API.
How should a permanent error response like HTTP:UNAUTHORIZED be handle inside Until Successful to reduce latency?
- A. Put the HTTP Request inside a try scope in Unit Successful.
In the error handler, use On Error Propagate to catch permanent errors like HTTP UNAUTHORIZED. - B. Put the HTTP Request inside a try scope in Unit Successful.
In the error handler, use On Error Continue to catch permanent errors like HTTP UNAUTHORIZED. - C. Configure retrying until a MULERETRY_EXHAUSTED error is raised or the API responds back with a successful response.
- D. In Until Successful configuration, set the retry count to 1 for error type HTTP: UNAUTHORIZED.
Answer: B
Explanation:
To handle a permanent error response like HTTP:UNAUTHORIZED inside Until Successful, the developer should put the HTTP Request inside a try scope in Unit Successful, and use On Error Continue to catch permanent errors like HTTP UNAUTHORIZED in the error handler. This way, the developer can avoid retrying requests that will always fail due to a permanent error, and reduce latency. On Error Continue allows the flow to continue processing after handling the error. Reference: https://docs.mulesoft.com/mule-runtime/4.3/until-successful-scope https://docs.mulesoft.com/mule-runtime/4.3/on-error-continue-concept
NEW QUESTION # 32
A company has been using CI/CD. Its developers use Maven to handle build and deployment activities.
What is the correct sequence of activities that takes place during the Maven build and deployment?
- A. Initialize, validate, compute, test, package, verify, install, deploy
- B. Validation, initialize, compile, test, package, install verify, deploy
- C. Validate, initialize, compile, package, test, install, verify, verify, deploy
- D. Validate, initialize, compile, test package, verify, install, deploy
Answer: D
Explanation:
The correct sequence of activities that takes place during the Maven build and deployment is validate, initialize, compile, test package, verify, install, deploy. These are Maven lifecycle phases that define a sequence of goals to execute during a build process. Each phase represents a stage in the build lifecycle and can have zero or more goals bound to it. Reference: https://maven.apache.org/guides/introduction/introduction-to-the-lifecycle.html
NEW QUESTION # 33
The HTTP Request operation raises an HTTP CONNECTIVITY error.
Which HTTP status code and body are returned to the web client?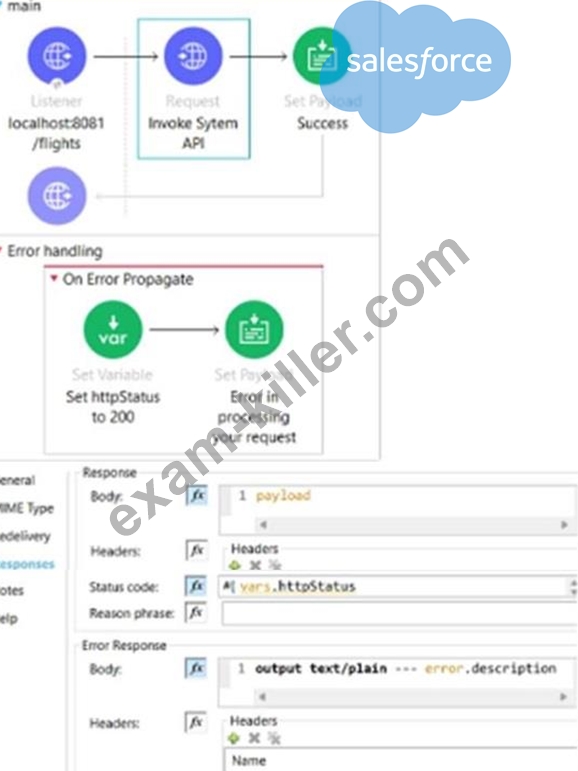
- A. HTTP Status Code:200.
Body 'Error in processing your request - B. HTTP Status Code:500.
Body 'Error in processing your request - C. HTTP Status Code:500.
Body 'Error in processing your request - D. HTTP Status Code:500.
Body 'The HTTP CONNECTIVITY Error description
Answer: C
Explanation:
When the HTTP Request operation raises an HTTP CONNECTIVITY error, it triggers an on-error-continue handler that sets a payload with 'Error in processing your request'. Since no status code is explicitly set in this handler, it defaults to 500 (INTERNAL SERVER ERROR). Therefore, the web client receives an HTTP response with status code 500 and body 'Error in processing your request'. Reference: https://docs.mulesoft.com/mule-runtime/4.3/error-handling#on-error-continue
NEW QUESTION # 34
Which command is used to convert a JKS keystore to PKCS12?
- A. Keytool-importkeystore -srckeystore keystore p12-srcstoretype PKCS12 -destkeystore keystore.jks -deststoretype JKS
- B. Keytool-importkeystore -srckeystore keystore p12-srcstoretype JKS -destkeystore keystore.p12 -deststoretype PKCS12
- C. Keytool-importkeystore -srckeystore keystore jks-srcstoretype JKS -destkeystore keystore.p13 -deststoretype PKCS12
- D. Keytool-importkeystore -srckeystore keystore jks-srcstoretype PKCS12 -destkeystore keystore.p12 -deststoretype JKS
Answer: B
Explanation:
To convert a JKS keystore to PKCS12, the developer needs to use the keytool-importkeystore command with the following options: -srckeystore keystore.jks -srcstoretype JKS -destkeystore keystore.p12 -deststoretype PKCS12. This command imports all entries from a source JKS keystore (keystore.jks) into a destination PKCS12 keystore (keystore.p12). Reference: https://docs.oracle.com/en/java/javase/11/tools/keytool.html#GUID-5990A2E4-78E3-47B7-AE75-6D1826259549
NEW QUESTION # 35
Refer to the exhibit.
What required changes can be made to give a partial successful response in case the United Airlines API returns with a timeout?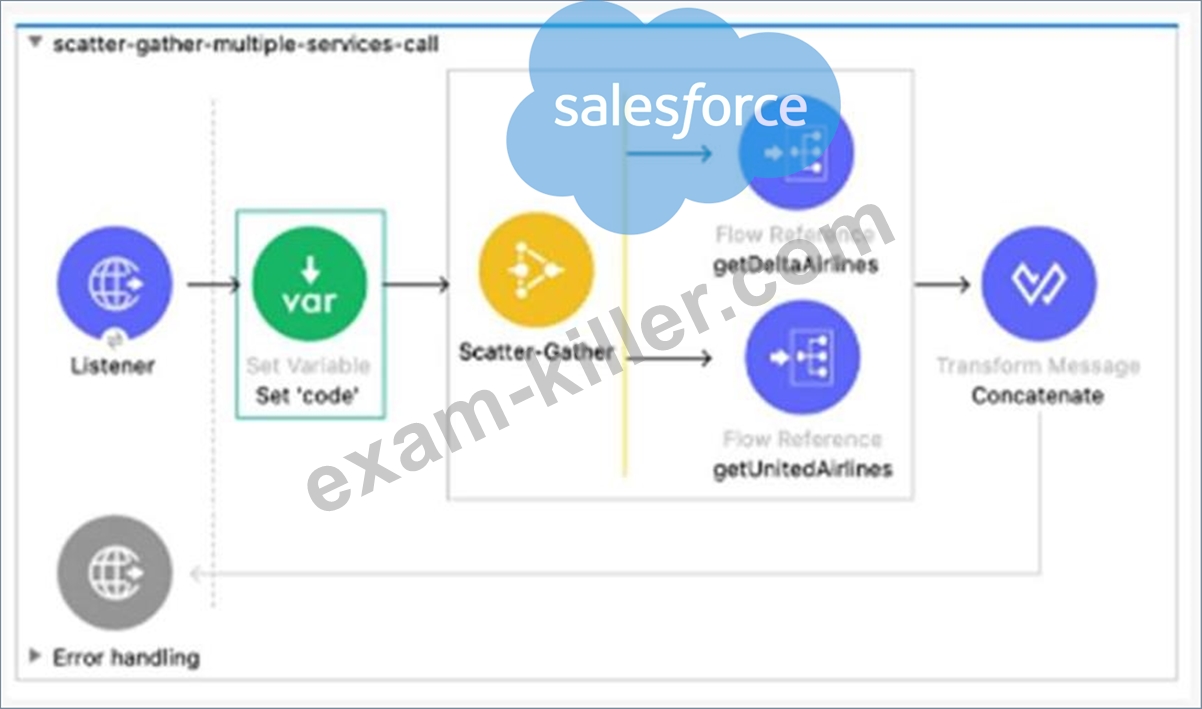
- A. Add Flow Reference components inside a Try scope
Set the payload to a default value '' inside the error handler using the On Error Propagate scope - B. Add a Scatter-gather component inside a Try scope.
Set the payload to a default value 'Error' inside the error handler using the On Error Propagate scope. - C. Add a Scatter-Gather component inside a Try scope.
Set the payload to a default value 'Error'' inside the error handler using the On Error Continue scope. - D. Add Flow Reference components inside a Try scope.
Set the payload to a default value'' insider the error handler using the ON Error Continue scope
Answer: C
Explanation:
To give a partial successful response in case the United Airlines API returns with a timeout, the developer should add a Scatter-Gather component inside a Try scope, and set the payload to a default value 'Error' inside the error handler using the On Error Continue scope. A Scatter-Gather component allows sending multiple requests concurrently and aggregating the responses into an array. A Try scope allows handling errors that occur within it using an error handler. An On Error Continue scope allows continuing the flow execution after handling an error. Therefore, by using these components, the developer can send requests to both APIs in parallel, handle any timeout errors from United Airlines API, and return a partial response with a default value for that API. Reference: https://docs.mulesoft.com/mule-runtime/4.3/scatter-gather-concept https://docs.mulesoft.com/mule-runtime/4.3/try-scope-concept https://docs.mulesoft.com/mule-runtime/4.3/on-error-continue-concept
NEW QUESTION # 36
Which statement is true when working with correlation IDS?
- A. The VM Connector does not automatically propagate correction IDs
- B. The HTTP Listener generates correlation IDS unless a correlation ID is received in the HTTP request
- C. The HTTP Listener regenerates correlation IDs regardless of the HTTP request
- D. The Anypoint MQ Connector automatically propagates correlation IDS
Answer: B
Explanation:
When working with correlation IDs, the HTTP Listener generates correlation IDs unless a correlation ID is received in the HTTP request. In that case, it propagates the received correlation ID throughout the flow execution. Correlation IDs are used to track events across different flows or applications. Reference: https://docs.mulesoft.com/mule-runtime/4.3/about-mule-message#message-attributes
NEW QUESTION # 37
An API has been developed and deployed to CloudHub Among the policies applied to this API is an allowlist of IP addresses. A developer wants to run a test in Anypoint Studio and does not want any policies applied because their workstation is not included in the allowlist.
What must the developer do in order to run this test locally without the policies applied?
- A. Deactivate the API in API Manager so the Autodiscovery element will not find the application when it runs in Studio
- B. Run the test as-s, with no changes because the Studio runtime will not attempt to connect to API Manager
- C. Pass in the runtime parameter ''-Danpow.platform.gatekeeper=disabled''
- D. Create a properties file specifically for local development and set the API instance ID to a value that is not used in API Manager
Answer: C
Explanation:
To run a test locally without the policies applied, the developer should create a properties file specifically for local development and set the API instance ID to a value that is not used in API Manager. This way, the developer can use different configuration properties for different environments and avoid triggering API autodiscovery when running tests locally. API autodiscovery is a mechanism that associates an API implementation with its corresponding API specification and policies in API Manager based on its API instance ID. By setting this ID to a value that does not exist in API Manager, the developer can prevent API autodiscovery from finding and applying any policies to the local test. Reference: https://docs.mulesoft.com/api-manager/2.x/api-auto-discovery-new-concept#configuring-api-autodiscovery https://docs.mulesoft.com/mule-runtime/4.3/configuring-properties
NEW QUESTION # 38
A company with MuleSoft Titanium develops a Salesforce System API using MuleSoft out-of-the-box Salesforce Connector and deploys the API to CloudHub.
Which steps provide the average number of requests and average response time of the Salesforce Connector?
- A. Access Anypoint Monitoring's built-in dashboard. Select a resource.
Locate the information under the Connectors tab. - B. Change the API Implementation to capture the information in the log.
Retrieve the information from the log file. - C. Access Anypoint Monitoring built-in dashboard.
Select a resource.
Locate the information under Log Manager < Raw Data. - D. Access Anypoint Monitoring's built-in dashboard
Seclect a resource.
Create a custom dashboard to retrieve the information.
Answer: A
Explanation:
To get the average number of requests and average response time of the Salesforce Connector, the developer should access Anypoint Monitoring's built-in dashboard, select a resource (such as an application or an API), and locate the information under the Connectors tab. The Connectors tab shows metrics for each connector used by the resource, such as average requests per minute, average response time, and failures. Reference: https://docs.mulesoft.com/monitoring/built-in-dashboard-reference
NEW QUESTION # 39
Which properties are mandatory on the HTTP Connector configuration in order to use the OAuth 2.0 Authorization Code grant type for authentication?
- A. Token URL, authorization URL, client ID, client secret local callback URL
- B. External callback URL, access token URL, client ID, response refresh token
- C. External callback URL, access token URL, client ID response access token
- D. External callback URL, access token URL, local authorization URL, authorization URL, client ID, client secret
Answer: D
Explanation:
To use the OAuth 2.0 Authorization Code grant type for authentication, the HTTP Connector configuration requires the following properties: token URL, authorization URL, client ID, client secret, and local callback URL. The token URL is the endpoint of the authorization server that provides access tokens. The authorization URL is the endpoint of the authorization server that initiates the user consent flow. The client ID and client secret are the credentials of the Mule application registered with the authorization server. The local callback URL is the endpoint of the Mule application that receives the authorization code from the authorization server. Reference: https://docs.mulesoft.com/http-connector/1.6/http-authentication#oauth-2-0
NEW QUESTION # 40
A Mule application contain two policies Policy A and Policy A has order1, and Policy B has order 2. Policy A Policy B, and a flow are defined by he configuration below.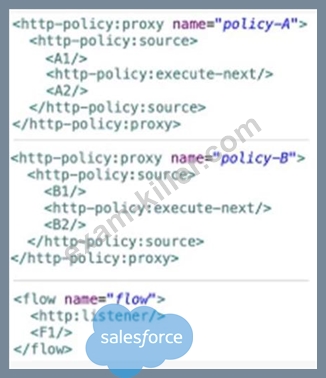
When a HTTP request arrives at the Mule application's endpoint, what will be the execution order?
- A. F1, A1, B1, B2, A2
- B. F1, B1, A1, A2, B2
- C. A1, B1, F1, B2, A2
- D. B1, A1, F1, A2, B2
Answer: C
Explanation:
Based on the configuration below, when a HTTP request arrives at the Mule application's endpoint, the execution order will be A1, B1, F1, B2, A2. This is because policies are executed before and after the API implementation flow according to their order attribute. Policy A has order 1, which means it is executed first before Policy B, which has order 2. The flow is executed after both policies are executed before the flow. Then, Policy B is executed after the flow before Policy A is executed after the flow. Reference: https://docs.mulesoft.com/api-manager/2.x/policies-policy-order
NEW QUESTION # 41
Mule application A is deployed to CloudHub and is using Object Store v2. Mute application B is also deployed to CloudHub.
Which approach can Mule application B use to remove values from Mule application A'S Object Store?
- A. Object Store Connector
- B. Object Store v2 REST API
- C. CloudHub REST API
- D. CloudHub Connector
Answer: B
Explanation:
To remove values from Mule application A's Object Store v2, Mule application B can use Object Store v2 REST API. This API allows performing operations on Object Store v2 resources using HTTP methods, such as GET, POST, PUT, and DELETE. Mule application B can use the DELETE method to remove values from Mule application A's Object Store v2 by specifying the object store ID and the key of the value to delete. Reference: https://docs.mulesoft.com/object-store/osv2-apis
NEW QUESTION # 42
A system API that communicates to an underlying MySQL database is deploying to CloudHub. The DevOps team requires a readiness endpoint to monitor all system APIs.
Which strategy should be used to implement this endpoint?
- A. Use an existing resource endpoint of the API
- B. Create a dedicated endpoint that responds with the API status only
- C. Create a dedicated endpoint that responds with the API status and reachability of the underlying systems
- D. Create a dedicated endpoint that responds with the API status and health of the server
Answer: C
Explanation:
To implement a readiness endpoint to monitor all system APIs, the developer should create a dedicated endpoint that responds with the API status and reachability of the underlying systems. This way, the DevOps team can check if the system API is ready to receive requests and if it can communicate with its backend systems without errors. Reference: https://docs.mulesoft.com/mule-runtime/4.3/deployment-strategies#readiness-probes
NEW QUESTION # 43
When registering a client application with an existing API instance or API Group instance, what is required to manually approve or reject request access?
- A. To configure the SLA tier for the application and have the role of Organization Administrator, API Manager Environment Administrator, or the Manage Contacts permission
- B. To only have Exchange Administrator permission
- C. To configure the SLA tier for the application and have the Exchange Administrator permission
- D. To configure the SLA tier for the application
Answer: B
Explanation:
To manually approve or reject request access when registering a client application with an existing API instance or API Group instance, it is required to configure the SLA tier for the application and have one of the following roles or permissions: Organization Administrator, API Manager Environment Administrator, or Manage Contracts permission. These roles or permissions allow managing client applications and contracts in API Manager. Reference: https://docs.mulesoft.com/api-manager/2.x/client-applications#managing-client-applications-and-contracts
NEW QUESTION # 44
A Flight Management System publishes gate change notification events whenever a flight's arrival gate changes. Other systems, including Baggage Handler System. Inflight Catering System and Passenger Notifications System, must each asynchronously receive the same gate change notification to process the event according.
Which configuration is required in Anypoint MQ to achieve this publish/subscribe model?
- A. Publish the gate change notification to an Anypoint MQ queue.
Create different anypoint MQ exchange meant for each of the other subscribing systems Bind the queue with each of the exchanges - B. Publish each client subscribe directly to the exchange.
Have each client subscribe directly to the queue. - C. Publish the gate change notification to an Anypoint MC queue
Have each client subscribe directly to the queue - D. Publish the gate change notification to an Anypoint MQ exchanhe.
Create different Anypoint MQ queues meant for each of the other subscribing systems.Bind the exchange with each of the queues.
Answer: D
Explanation:
To achieve a publish/subscribe model using Anypoint MQ, where each system receives the same gate change notification event, the developer should publish the gate change notification to an Anypoint MQ exchange, create different Anypoint MQ queues meant for each of the other subscribing systems, and bind the exchange with each of the queues. An exchange is a message routing agent that can send messages to different queues based on predefined criteria. By binding an exchange with multiple queues, each queue receives a copy of every message sent to that exchange. Therefore, each system can subscribe to its own queue and receive every gate change notification event. Reference: https://docs.mulesoft.com/anypoint-mq/3.x/anypoint-mq-exchanges
NEW QUESTION # 45
Refer to the exhibit.
A Mute Object Store is configured with an entry TTL of one second and an expiration interval of 30 seconds.
What is the result of the flow if processing between os'store and os:retrieve takes 10 seconds?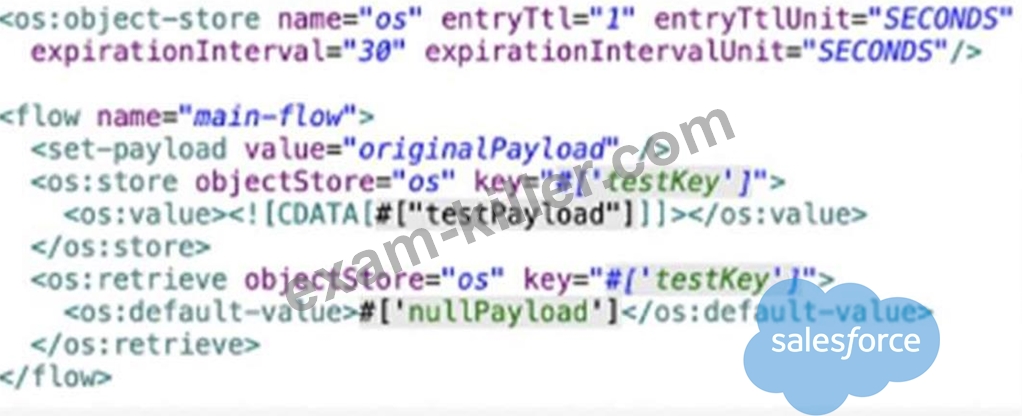
- A. testPayload
- B. originalPayload
- C. nullPayload
- D. OS:KEY_NOT_FOUND
Answer: C
Explanation:
The result of the flow is nullPayload if processing between os:store and os:retrieve takes 10 seconds. This is because the entry TTL of the object store is one second, which means that any stored value expires after one second and is removed from the object store. The expiration interval of 30 seconds only determines how often the object store checks for expired values, but it does not affect the TTL. Therefore, when os:retrieve tries to get the value after 10 seconds, it returns nullPayload because the value has already expired and been removed. Reference: https://docs.mulesoft.com/object-store/osv2-faq#how-does-the-time-to-live-work
NEW QUESTION # 46
An organization uses CloudHub to deploy all of its applications.
How can a common-global-handler flow be configured so that it can be reused across all of the organization's deployed applications?
- A. Create a Mule Plugin project
- B. Create a common-global-error-handler flow in all Mule Applications Refer to it flow-ref wherever needed.
- C. Create a Mule plugin project
Create a common-global-error-handler flow inside the plugin project.
Use this plugin as a dependency in all Mute applications.
Import that configuration file in Mute applications.
Answer: A
Explanation:
Create a common-global-error-handler flow inside the plugin project.
Use this plugin as a dependency in all Mule applications
D.
Create a Mule daman project.
Create a common-global-error-handler flow inside the domain project.
Use this domain project as a dependency.
Explanation:
To configure a common-global-handler flow that can be reused across all of the organization's deployed applications, the developer should create a Mule Plugin project, create a common-global-error-handler flow inside the plugin project, and use this plugin as a dependency in all Mule applications. This way, the developer can import the common-global-error-handler flow in any application that needs it and avoid duplicating the error handling logic. Reference: https://docs.mulesoft.com/mule-runtime/4.3/error-handling#global-error-handler
NEW QUESTION # 47
A Mule application need to invoice an API hosted by an external system to initiate a process. The external API takes anywhere between one minute and 24 hours to compute its process.
Which implementation should be used to get response data from the external API after it completes processing?
- A. Use an HTTP Connector inside Async scope to invoice the API and wait for a response
- B. Expose an HTTP callback API in Mule and register it with the external system
- C. Use a Scheduler to check for a response every minute
- D. Use an HTTP Connector to invoke the API and wait for a response
Answer: B
Explanation:
To get response data from the external API after it completes processing, the developer should expose an HTTP callback API in Mule and register it with the external system. This way, the external API can invoke the callback API with the response data when it is ready, instead of making the Mule application wait for a long time or poll for a response repeatedly. Reference: https://docs.mulesoft.com/mule-runtime/4.3/http-listener-ref#callback
NEW QUESTION # 48
A company deploys 10 public APIs to CloudHub. Each API has its individual health endpoint defined. The platform operation team wants to configure API Functional Monitoring to monitor the health of the APIs periodically while minimizing operational overhead and cost.
How should API Functional Monitoring be configured?
- A. From 10 public locations with each API in its own schedule
- B. From one public location with all 10 APIs in a single schedule
- C. From one public location with each API in its own schedule
- D. From one private location with all 10 APIs in a single schedule
Answer: B
Explanation:
To configure API Functional Monitoring to monitor the health of 10 public APIs periodically while minimizing operational overhead and cost, the developer should use one public location with all 10 APIs in a single schedule. A public location is a worker that runs in a CloudHub shared environment, which is cheaper and easier to maintain than a private location. A single schedule allows running all 10 APIs tests at the same time and frequency, which reduces complexity and resource consumption. Reference: https://docs.mulesoft.com/functional-monitoring/fm-create-monitor#create-a-monitor
NEW QUESTION # 49
Refer to the exhibit.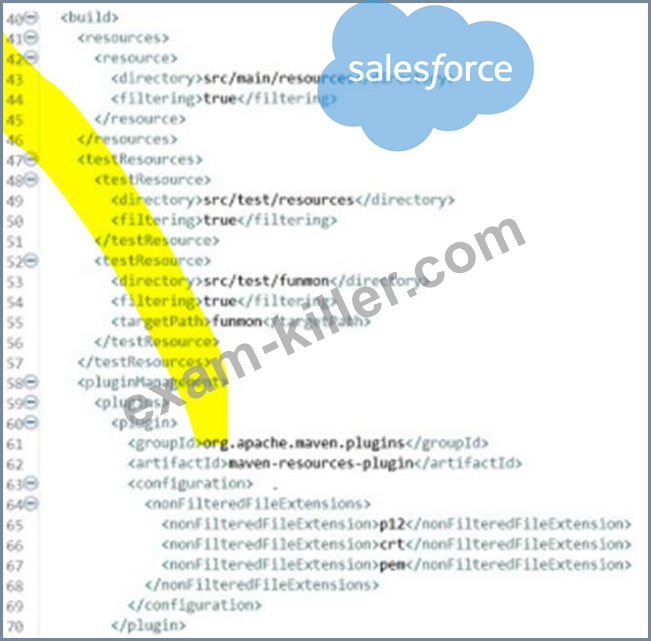
A Mule application pom.xml configures the Maven Resources plugin to exclude parsing binary files in the project's src/main/resources/certs directory.
Which configuration of this plugin achieves a successful build?
- A.
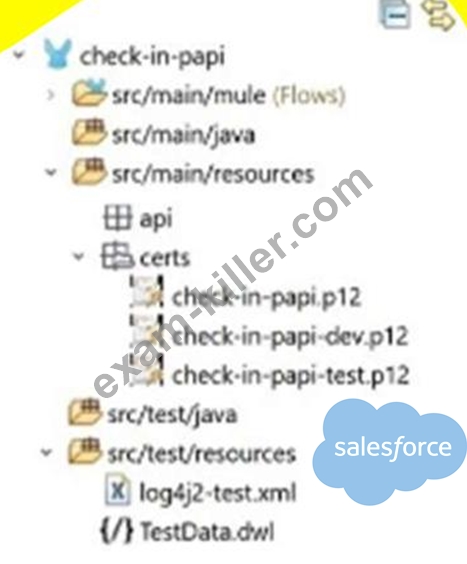
- B.
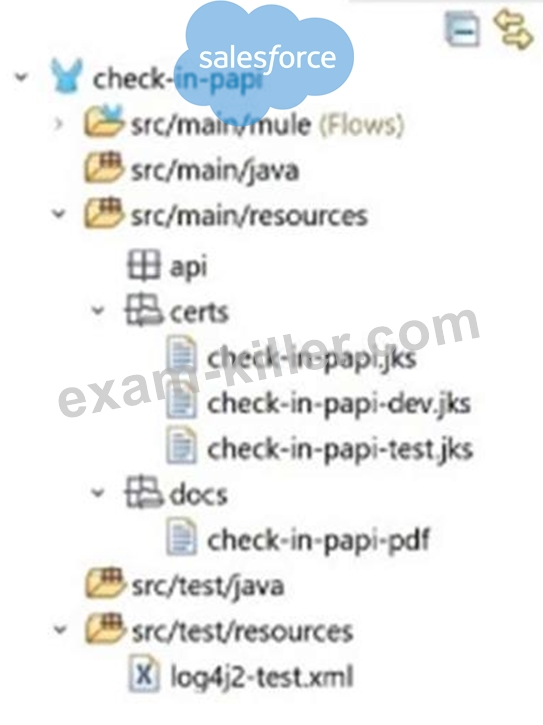
- C.
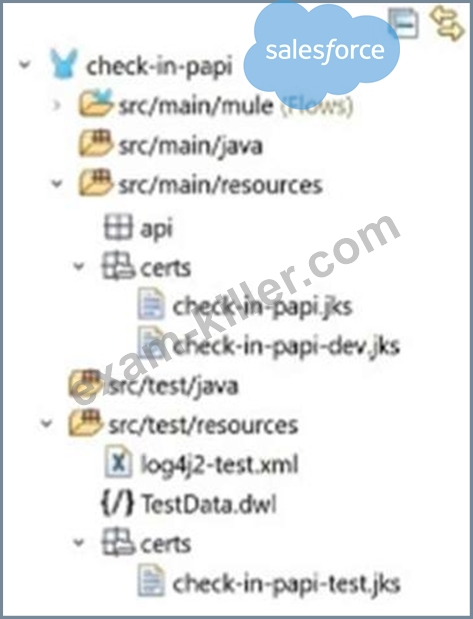
- D.
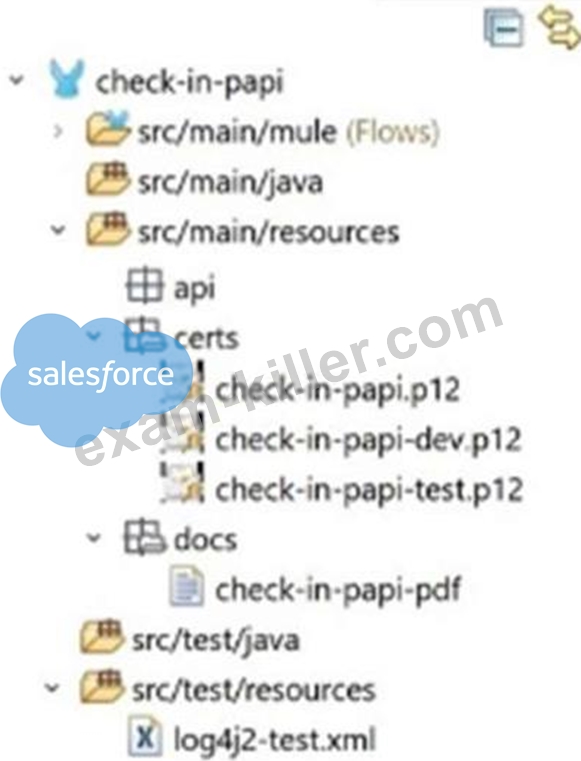
Answer: D
Explanation:
To configure the Maven Resources plugin to exclude parsing binary files in the project's src/main/resources/certs directory, option C should be used. This option specifies that any files with .cer or .jks extensions under the certs directory should be excluded from filtering. Filtering is a process of replacing placeholders with actual values in resource files during the build process. Binary files should not be filtered because they may become corrupted or unusable. Reference: https://maven.apache.org/plugins/maven-resources-plugin/examples/filter.html https://maven.apache.org/plugins/maven-resources-plugin/examples/include-exclude.html
NEW QUESTION # 50
An order processing system is composed of multiple Mule application responsible for warehouse, sales and shipping. Each application communication using Anypoint MQ. Each message must be correlated against the original order ID for observability and tracing.
How should a developer propagate the order ID as the correlation ID across each message?
- A. Wrap all Anypoint MQ Publish operations within a With CorrelationID scope from the Tracing module, setting the correlation ID to the order ID
- B. Use the underlying HTTP request of Anypoint MQ to set the 'X-CORRELATION_ID' header to the order ID
- C. Set a custom Anypoint MQ user property to propagate the order ID and set the correlation ID in the receiving applications.
- D. Use the default correlation ID, Anypoint MQ will sutomatically propagate it.
Answer: A
Explanation:
To propagate the order ID as the correlation ID across each message using Anypoint MQ, the developer should wrap all Anypoint MQ Publish operations within a With CorrelationID scope from the Tracing module, setting the correlation ID to the order ID. The With CorrelationID scope allows setting a custom correlation ID for any event that occurs within it. The Tracing module also enables distributed tracing across different Mule applications and services using Anypoint Monitoring. Reference: https://docs.mulesoft.com/tracing-module/1.0/tracing-module-reference#with-correlation-id-scope https://docs.mulesoft.com/tracing-module/1.0/tracing-module-concepts
NEW QUESTION # 51
Which pattern should be used to invoke multiple HTTP APIs in parallel and roll back failed requests in sequence?
- A. Scatter-Gather as central Saga orchestrator for all API request with compensating actions for failing routes
- B. A Parallel for Each scope with each HTTP request wrapped in a Try scope
- C. A database as a transactional outbox and an Until Successful router to retry any requests
- D. VM queues as a reliability pattern with error handlers to roll back any requests
Answer: A
Explanation:
To invoke multiple HTTP APIs in parallel and roll back failed requests in sequence, the developer should use a Scatter-Gather router as a central Saga orchestrator for all API requests with compensating actions for failing routes. A Scatter-Gather router executes multiple routes concurrently and aggregates the results. A Saga orchestrator coordinates a series of actions across different services and handles failures by executing compensating actions. Therefore, using a Scatter-Gather router as a Saga orchestrator allows invoking multiple HTTP APIs in parallel and rolling back any failed requests in sequence. Reference: https://docs.mulesoft.com/mule-runtime/4.3/scatter-gather-concept https://docs.mulesoft.com/mule-runtime/4.3/saga
NEW QUESTION # 52
......
Latest 2026 Realistic Verified Mule-Dev-301 Dumps: https://www.exam-killer.com/Mule-Dev-301-valid-questions.html
Pass Mule-Dev-301 Exam Updated 62 Questions: https://drive.google.com/open?id=1kOZu0lZ-gjnguOW7Dv2oLEkbWMu7mo1U
